How to Route Monitoring Alerts to the Right Team
Organize alert rooms by service ownership and severity, then forward actionable state changes with deduplication and correlation data.
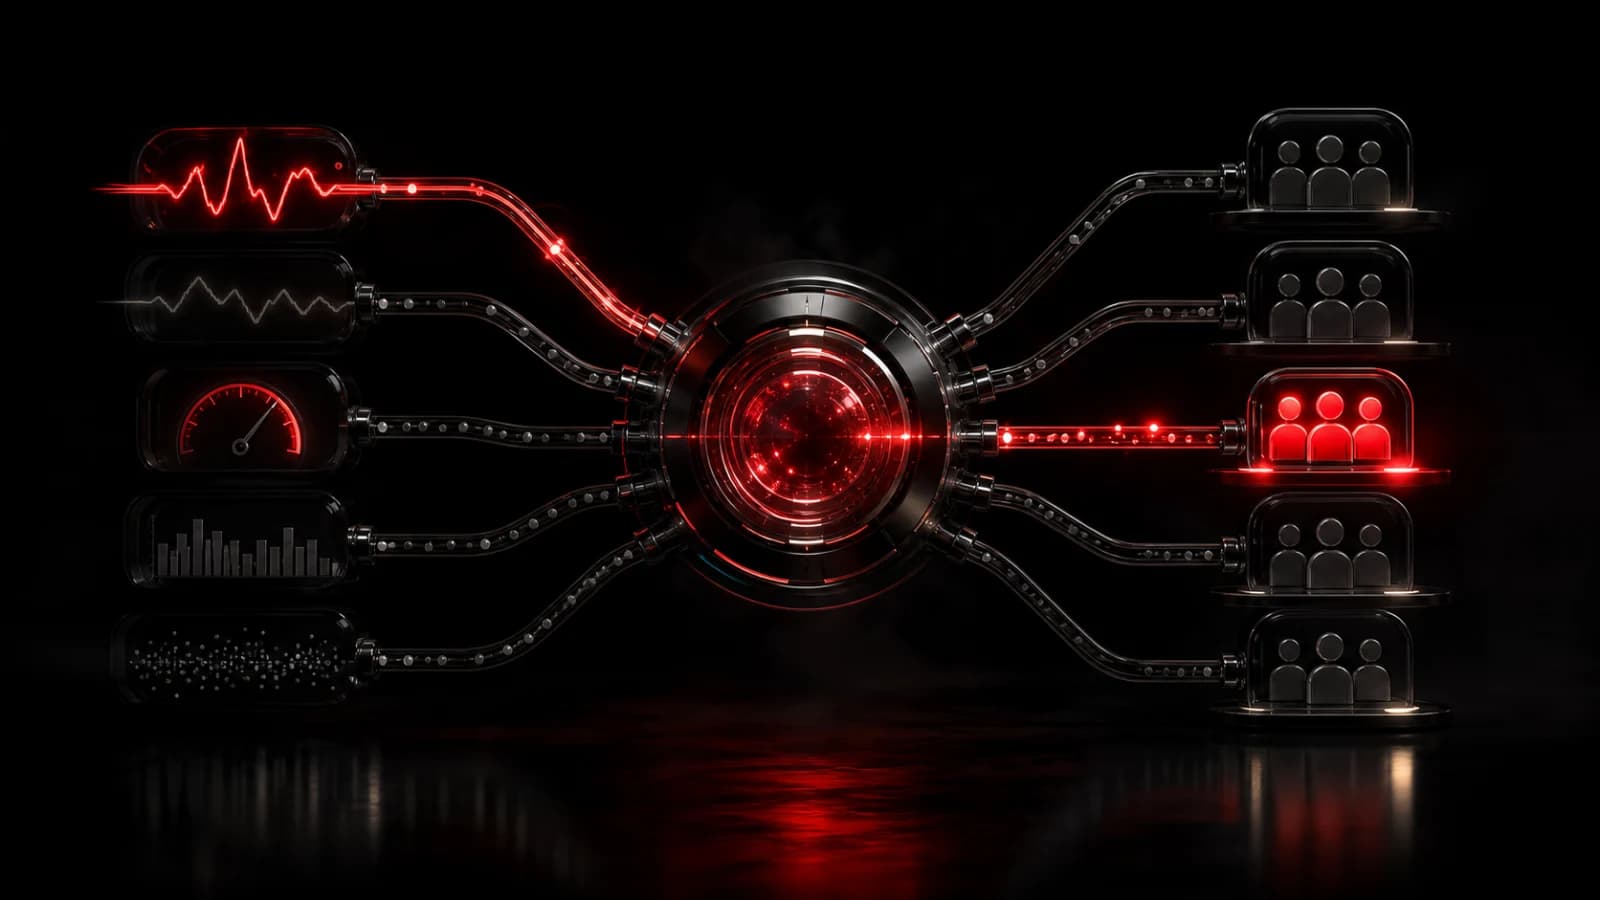
The useful unit for monitoring is not “everyone who works in engineering.” It is the team that owns the affected service at the current severity. Create PingRoom rooms around that ownership, then route webhook events accordingly.
Define the routing table
Map service or component labels to a destination room. Keep a separate path for high-severity incidents if they require a distinctive sound or acknowledgement. Unknown ownership should fall back to an actively monitored triage room, not disappear silently.
Forward state transitions—Firing, Escalated, and Recovered—rather than every evaluation. Include the service, environment, severity, safe incident URL, and event identifier. Use correlation_id to associate the recovery with the original incident.
Deduplicate retries and apply cooldowns to flapping checks. Test routing whenever ownership metadata changes. A beautifully formatted alert in the wrong room is still a missed alert.
Preserve the real incident system
PingRoom is the attention destination, not the source of truth for alert evaluation, escalation schedules, or audit history. Critical monitoring should retain redundant paging and the incident system’s native records. Push delivery can be affected by connectivity, device settings, and provider delays.
Keep tokens, raw request content, customer data, and sensitive logs out of notifications. Store each incoming webhook URL as a credential with access limited to the routing service.
Start with server-down alerts, then use structured Pings when automation needs machine-readable context.
For a concrete Grafana setup, verify one selected Grafana alert at a relay, forward fixed firing or resolved copy, and keep alert detail and incident response in Grafana.
If Prometheus Alertmanager owns the route, send one selected alert instance through an authenticated relay and keep grouping, silences, inhibition, and escalation in the monitoring stack.
If BugSnag owns the error record, send one selected new production error through a privacy-minimizing relay, keep the diagnostic payload in BugSnag, and treat its secret relay path as a bearer credential rather than signed sender proof.
If Honeycomb owns the Trigger, send one selected TRIGGERED or OK transition through a shared-secret relay, map the stable delivery ID to replay-safe PingRoom delivery, and keep the query, threshold, groups, and investigation in Honeycomb.
If Rollbar owns the error item, send one selected New Item event through a privacy-minimizing relay, keep item and occurrence details in Rollbar, and treat the configured URL token as a bearer credential rather than signed sender proof.
If CloudWatch owns the alarm, try AWS-native mobile push first. When a stable group instead needs one shared Room signal, route one exact alarm state change through EventBridge and a narrow Lambda, keep the reason and metric in AWS, and treat OK as an evaluation state rather than proof of recovery.

PingRoom
Short-form communication.